Distributed quantum architecture & compilation · UT Austin ACES · EuroSys 2027 (accepted)
IRIS
Teleportation-aware instruction scheduling for distributed quantum computers with limited EPR-pair capacity.
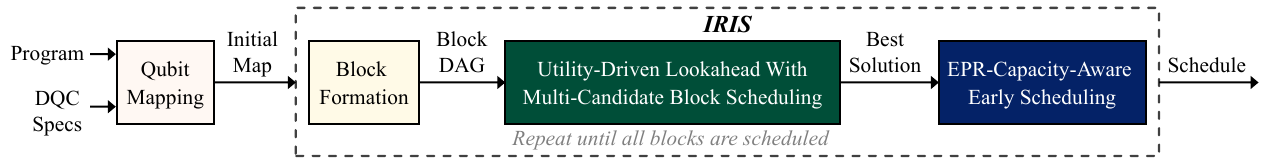
Overview
Distributed quantum computers connect smaller quantum chips through photonic interconnects. Non-local CNOTs then require state teleportation (RELOCATE) or gate teleportation (Re-CNOT), making inter-chip operations slower and more error-prone than local gates.
IRIS targets low-level instruction scheduling and is orthogonal to the initial mapping policy. The evaluation uses modular dual-species neutral-atom processors with separate compute and communication qubits, where the available communication qubits determine each chip’s EPR capacity.
Design
Utility-Driven Lookahead with Multi-Candidate Block Scheduling (UMS)
Look ahead only to future blocks that share qubits with the current block, while retaining the top-w candidate schedules to avoid early commitment.
EPR-Capacity-Aware Early Scheduling (EES)
Move dependency-resolved future CNOTs and their teleportations across block boundaries when doing so adds no relocation and preserves available EPR capacity.
Key results
Relative to QuComm, IRIS reduces effective teleportation count by 34% on average (up to 65%) and improves program-schedule latency by 2.0× on average (up to 2.9×).
These are schedule-level results, not compilation speedups. Larger programs take longer to compile; the paper evaluates that trade-off over repeated shots. The QEC-cycle comparison uses a 2×2 DQC.
People
-
 Won Joon Yun
-
Dhilan Nag
-
Sneha Ballabh
-
 Jiapeng Zhao
-
Eneet Kaur
-